Research / 2025
Your Text Encoder Can Be An Object-Level Watermarking Controller
Published in IEEE/CVF International Conference on Computer Vision (ICCV), 2025
Overview
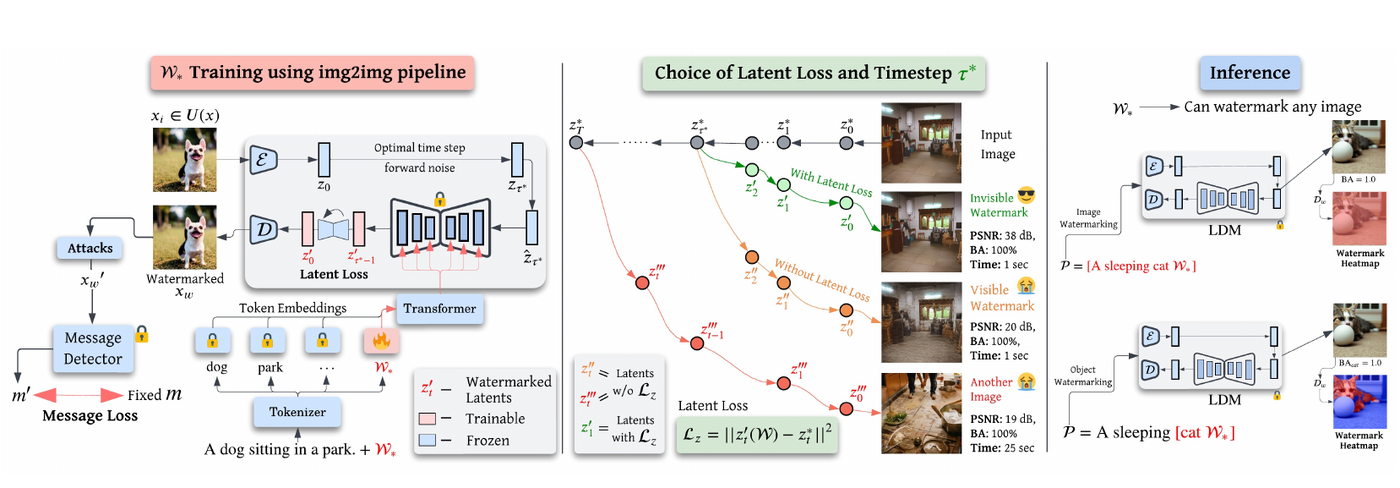
Watermarking need not apply uniformly to a whole generated image. This work learns a text token that can control a watermark globally or steer it toward selected objects.
How it works
- Learn a 768-dimensional watermark-token embedding while keeping the pretrained generation components fixed.
- Train the token through an image-to-image generation objective and a pretrained watermark decoder.
- Use cross-attention maps and latent controls to target prompt-selected objects during generation.
The paper also examines compatibility with personalized models and textual-inversion concepts.
A reported result
0.99 bit accuracy with a 48-bit payload for the MS-COCO, full-image Stable Diffusion setting without attacks, Table 1.
That is per-bit recovery, not the probability that every message is recovered exactly. Object-level experiments and robustness after image transformations are evaluated separately.
Scope
The clean full-image result does not imply identical recovery for every isolated or cropped object. Watermark placement and recovery depend on attention localization, selected regions, and subsequent transformations.
Source
Bibliographic reference
Naresh Kumar Devulapally, Mingzhen Huang, Vishal Asnani, Shruti Agarwal, Siwei Lyu, Vishnu Suresh Lokhande. (2025). Your Text Encoder Can Be An Object-Level Watermarking Controller.